Industry Track
Industry Program
Sunday, October 25, 2026
| Start | End | Session Number | Description |
|---|---|---|---|
| 11:00 | 12:30 | Session 2 | Industry 1: Opening, Invited Talk: Mohit Bansal, Oral talk |
| 16:30 | 18:00 | Session 4 | Industry 2: Retrieval and RAG |
Monday, October 26, 2026
| Start | End | Session Number | Description |
|---|---|---|---|
| 9:00 | 10:30 | Session 5 | Industry 3: Invited Speaker: Verena Rieser, 2 oral talks |
| 11:00 | 12:30 | Session 6 | Industry: Poster Session |
| 16:45 | 18:15 | Session 9 | Industry 4: Trust, Safety, and Control |
Tuesday, October 27, 2026
| Start | End | Session Number | Description |
|---|---|---|---|
| 9:00 | 10:30 | Session 10 | Industry 5: Agents in Production |
| 11:00 | 12:30 | Session 11 | Industry 6: Oral talk, Panel, Closing |
Industry Keynote 1: Mohit Bansal
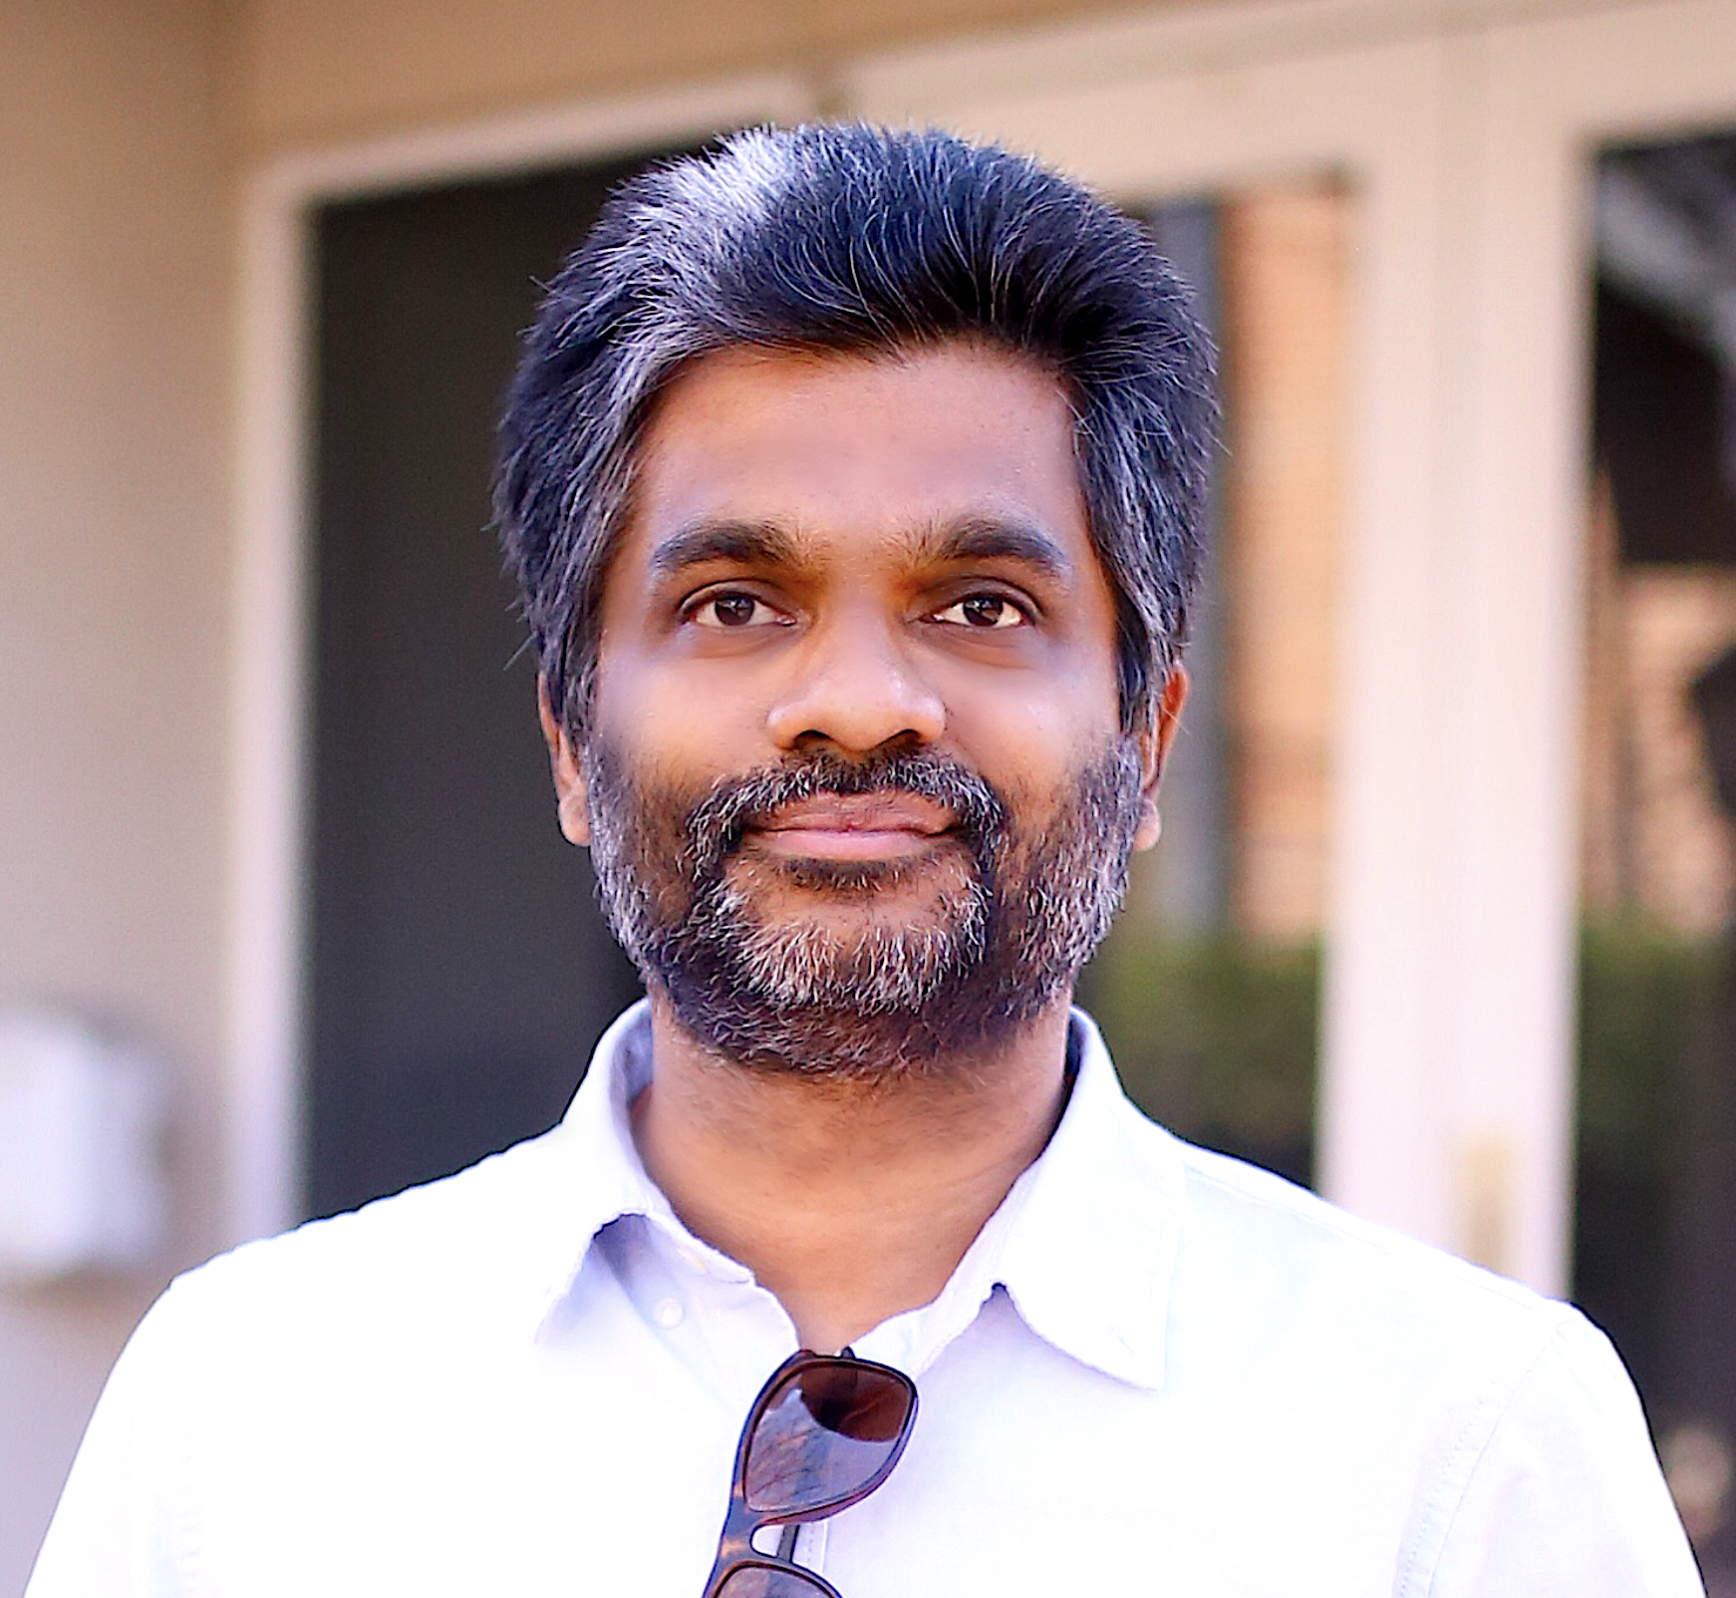
Sunday, October 25, 11:00 – 12:30
Title: Agentic Challenges (Trustworthy Collaboration, World Discovery, and Long-Horizon Memory) and Industry-Academia Collaborations
Abstract: In this talk, I will discuss 3 major pitfalls and challenges of current state-of-the-art AI agents, and present potential solutions for: (1) Teaching agents to be trustworthy and reliable collaborators based on: social/pragmatic multi-agent interactions via speaker-listener confidence calibration, learning to balance positive and negative persuasion, and multi-agent AI safety through the lens of compositional attacks, theory-of-mind, and belief-steering; (2) Discovering and improving skills/world models needed for efficient, robust action and collaboration based on: learning programmatic skills, weakness-driven adaptive data/environment generation for skill improvement, and structured, selective world model discovery and inference; (3) Planning of long-horizon memory for multi-step reasoning and generation over continuously evolving, conflicting, and scattered information. We will cover diverse domains (math, commonsense, coding, tool-use, computer use, etc.), modalities (text, images, videos, audio, layouts, etc.), and real-world applications (early medical diagnosis and classroom education engagement). I will end the talk with a journey of industry-academia collaborations and thoughts on how to re-bridge and strengthen this important relationship in our current AI community going forward.
Bio: Dr. Mohit Bansal is the John R. & Louise S. Parker Distinguished Professor, Director of the MURGe-Lab (UNC-AI Group), and Core AI Lead of the ENGAGE NSF-AI Institute in the Computer Science department at UNC Chapel Hill. He received his PhD from UC Berkeley and his BTech from IIT Kanpur. His research expertise is in multimodal generative models, reasoning and planning agents, faithful language generation, and interpretable, efficient, and generalizable deep learning. He is an ACL and AAAI Fellow and recipient of the Presidential Early Career Award for Scientists and Engineers (PECASE), IIT Kanpur Young Alumnus Award, DARPA Director’s Fellowship, NSF CAREER Award, Google Focused Research Award, Microsoft Investigator Fellowship, Army Young Investigator Award (YIP), DARPA Young Faculty Award (YFA), and outstanding paper awards at ACL, CVPR, EACL, COLING, CoNLL, and TMLR. He has been a keynote speaker for the IEEE/CVF WACV 2027, IEEE MLSP 2026, ECAI 2025, ACM-CODS 2025, AACL-IJCNLP 2023, CoNLL 2023, and INLG 2022 conferences. His service includes EMNLP Program Co-Chair, Associate Editor-in-Chief for TPAMI, CoNLL Program Co-Chair, ACL Executive Committee, ACM Doctoral Dissertation Award Committee, ACL Doctoral Dissertation Award Co-Organizer, ACL Mentorship Program Co-Founder, and Associate Editor for ACM AI Letters, TACL, CL, IEEE/ACM TASLP, and CSL journals. Webpage: https://www.cs.unc.edu/~mbansal/
Industry Keynote 2: Verena Rieser
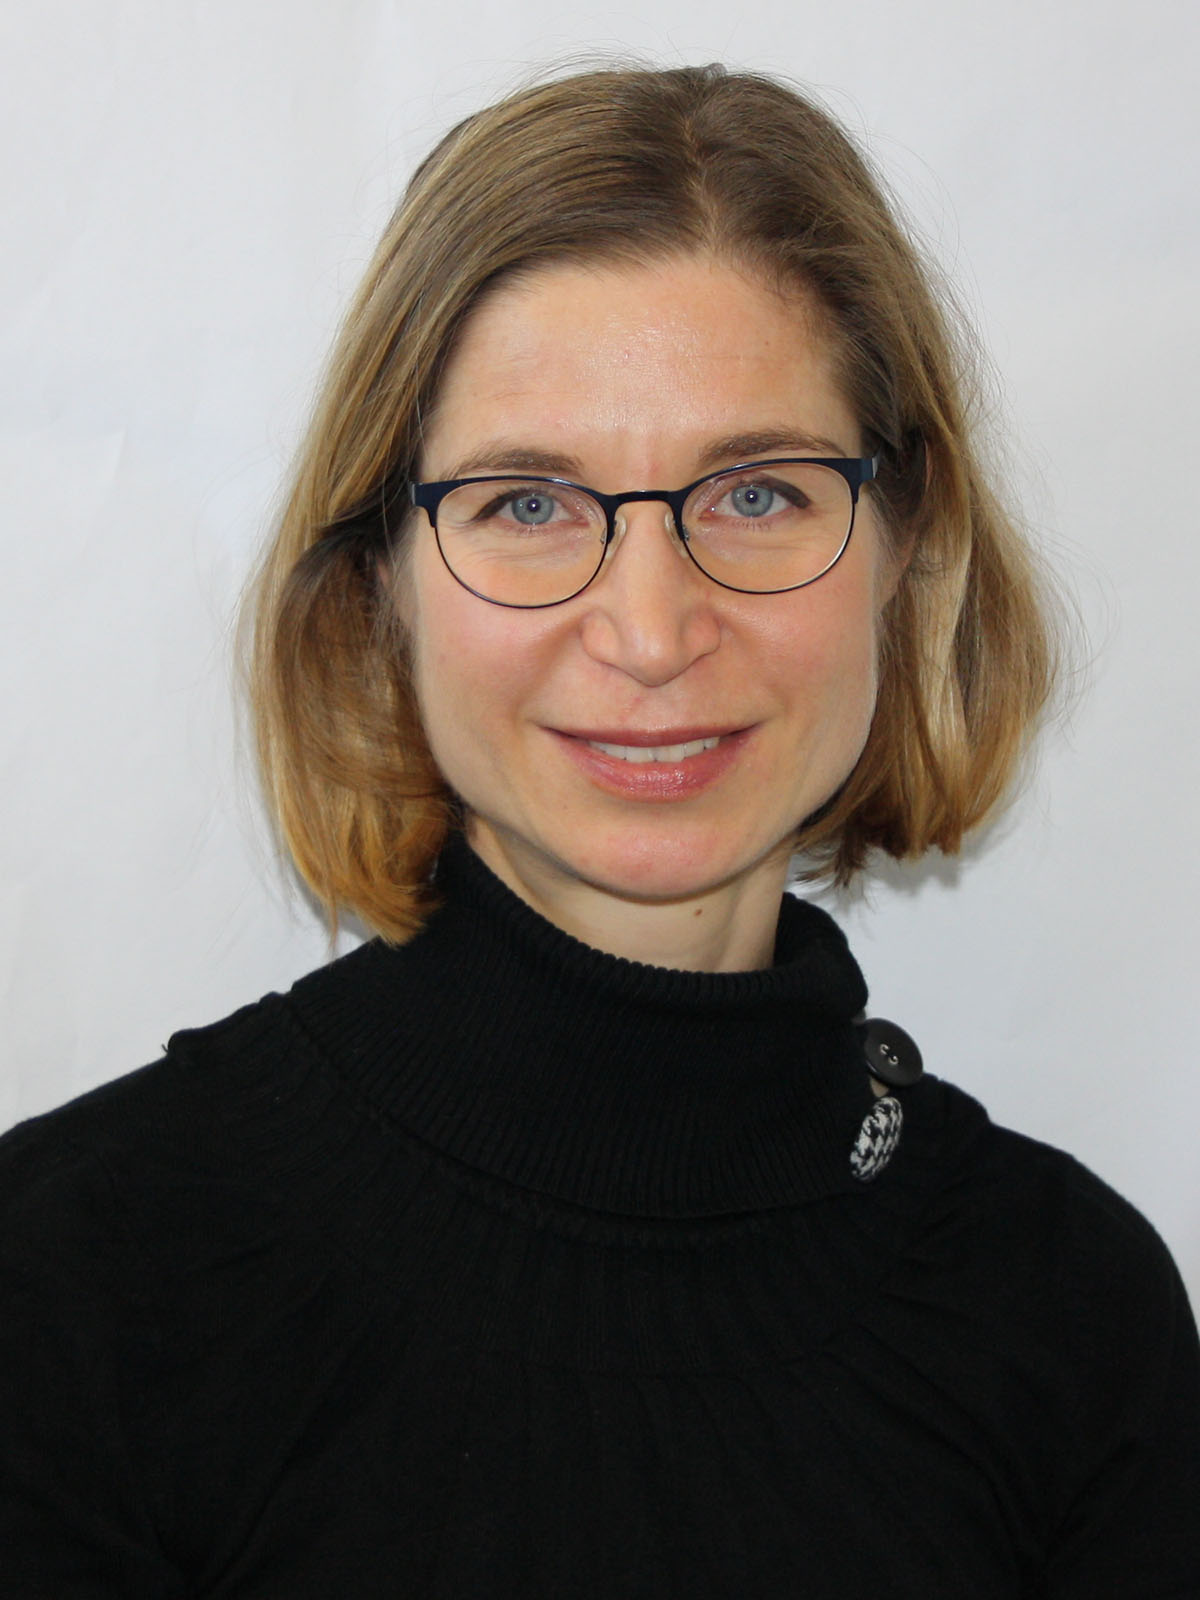
Monday, October 26, 9:00 – 10:30
Title: What are we aligning to? Positive Alignment for Value-based Agents
Abstract: Outcome-driven metrics hack safety constraints, human preferences breed sycophancy, and rigid rubrics fail out-of-distribution. This talk makes the case for positive alignment: anchoring agents in values and principles for autonomous decision-making. To realise this vision, I argue that current constitutional approaches leave two foundational questions unanswered. First, can models apply abstract values and principles out of the box? I will demonstrate why existing models fall short and outline the need to evaluate and cultivate genuine normative reasoning. Second, where do these values come from? I show how scalable democratic deliberation can derive shared normative principles. Finally, I demonstrate how this dual agenda provides the necessary foundation for preventing systemic safety traps and coordination failures in multi-agent ecosystems.
Speaker Bio: Verena Rieser is a Research Lead at Google DeepMind, where she directs research on responsible alignment for frontier models. She has over 20 years of experience researching and building generative and conversational AI systems. She was previously a Full Professor of Artificial Intelligence at Heriot-Watt University and co-founder of an AI startup. She earned her PhD from Saarland University in 2008, where she pioneered the use of reinforcement learning for spoken dialogue systems.
Her foundational contributions to conversational AI and machine learning have been recognized with numerous international honours, including a Royal Society Leverhulme Trust Senior Research Fellowship. Following her ACL 2025 Keynote on pluralistic alignment and her ICML 2026 Keynote on principled agency, her work establishes a human-centred roadmap for navigating the critical transition from passive chatbots to autonomous beneficial agents.
Panel: October 27, Session 11:00–12:30
Topic: AI Agents in the Real World: Capability, Trust, Values, and Deployment
Context: Large language models are rapidly evolving from systems that generate responses into agents that pursue goals, use tools, maintain memory, interact with people and other agents, and act across extended periods of time. Yet greater agency brings more than greater capability: it introduces new questions about reliability, control, accountability, values, and the appropriate division of labour between humans and machines. An agent may succeed on a benchmark while failing under changing, ambiguous, or adversarial real-world conditions; it may complete a task while violating the user’s underlying intent; and it may appear collaborative while manipulating beliefs or merely agreeing with its user. This panel brings together perspectives from research and industry to examine what meaningful progress in AI agents should look like, how it should be evaluated, and what technical, institutional, and societal foundations are needed before increasingly autonomous agents can be deployed responsibly at scale.